Portfolio Selected AI work →

AI that makes it to production.

We design, build and deploy AI platforms, agents and pipelines — grounded in your data, governed, and engineered to scale. From a first prototype to an air-gapped enterprise deployment, we own the whole path.

10+ years building software200+ clients 1M+ users on products we've shipped Deployed on-prem, in VPC and in the cloud
team capacity — this sprint28 engineers
SKML engineers7/8
MRBackend6/8
AHFrontend5/6
ZNDesign & UX2/3
TFQA & evals2/4
RBDevOps3/5
Available in 2 weeks6
techtix — delivery board 9 active engagements ⌘K
client engagement stageprogress podweek
GUGovernment of UAE Scale RDQ wk 31
MGMidis Group Harden MU wk 9
OCOhm Connect Prototype RD wk 3
CDCastle Digital Prototype QM wk 2
XGXergy Ground D wk 2
ACAtlas Consulting Frame M wk 1
SSSecuritySnares Frame U wk 1
SHIPPED THIS QUARTER
M-agnt — on-prem rolloutLive
MAIA — conversational layerLive
PepTracker — AI insightsLive
Banch — campaign generationIn build

trusted by

Government of UAE
Government of KSA
Majid Al Futtaim
Midis Group
Castle Digital
Xergy
Ohm Connect
Inter Digital
Eventflo
SecuritySnares
Atlio
Atlas Consulting

Most AI projects die between the demo and the deployment.

Getting a language model to produce something impressive takes an afternoon. Getting it to answer correctly, every time, against your real data, inside your security perimeter, at a cost you can defend — that is the actual project. It is also where most engagements stall.

Fig 0.1

It isn't grounded

A model answering from its training weights instead of your systems will be confidently wrong, and no one downstream can tell which answers to trust.

Fig 0.2

It isn't governed

No access control at the retrieval layer, no audit trail, no lineage. Fine for a prototype. Disqualifying for anyone with a compliance obligation.

Fig 0.3

It doesn't survive scale

Latency, token cost and hallucination rate all behave differently at a thousand users than at ten. Architecture decided in week one decides whether that hurts.

We start where the demos stop.

What we do

Five ways we put AI into production.

Whether you are building an AI-native product from zero, adding intelligence to software you already run, or automating work that currently eats your team's week — the engineering underneath is the same discipline.

End-to-end AI products, from problem statement to production deployment.

We build complete AI platforms: the model layer, the retrieval layer, the orchestration, the interface, the infrastructure and the governance around it. You get a product, not a proof of concept.

  • Multi-agent platforms and agent orchestration
  • Conversational interfaces with native voice, screen and document input
  • Natural-language interfaces over structured enterprise data
  • Human-in-the-loop workflows where review and approval actually matter
  • On-premise, VPC, air-gapped and cloud deployment
  • Full product surface — UI/UX, backend, APIs, admin and analytics

Your product already works. We make it intelligent without rebuilding it.

Most companies do not need a new platform — they need the one they have to do more. We retrofit AI into existing codebases, working with your architecture rather than around it, and ship in increments you can evaluate.

  • Legacy codebase audit and AI-readiness assessment
  • Conversational layers over existing data and dashboards
  • AI-generated insights, summaries and reports inside your current UI
  • Natural-language analytics and on-demand visualisation
  • Intelligent triage, routing, scoring and classification
  • Incremental rollout with feature flags — no big-bang rewrites

The difference between an AI that guesses and an AI that knows.

Retrieval is where accuracy is won or lost. We build ingestion and retrieval pipelines that connect models to your documents, databases and systems — with access control enforced at retrieval, not at display, and every answer traceable to its source.

  • Document, database and API ingestion at enterprise scale
  • Chunking, embedding and indexing strategies tuned to your content
  • Hybrid, semantic and graph-based retrieval
  • Re-ranking, query rewriting and context assembly
  • Role-based access control enforced at the query layer
  • Citation, lineage and audit trails on every response
  • Retrieval evaluation harnesses so quality is measured, not assumed

When an off-the-shelf model is the wrong answer.

Sometimes the general-purpose model is too expensive, too slow, too generic, or simply not allowed to see your data. We train and fine-tune models that are yours — smaller, cheaper, more accurate on your domain, and deployable inside your own infrastructure.

  • Fine-tuning open-weight and proprietary models on domain data
  • Custom machine learning and predictive models
  • Training data curation, labelling strategy and synthetic data generation
  • Evaluation suites, benchmarks and regression testing for model changes
  • Model distillation and quantisation for cost and latency
  • Self-hosted inference and serving infrastructure
  • Ongoing monitoring for drift, degradation and cost

Automate the work, not just the clicks.

We build agents and automations that carry out real multi-step work across your tools — with the guardrails, approvals and observability that make them safe to leave running.

  • Task-specific and multi-agent systems with tool use
  • Automations across Salesforce, HubSpot, Slack, Google Workspace and internal APIs
  • Document, email and ticket processing at volume
  • Robotic process automation for legacy systems with no API
  • Approval gates, escalation paths and human-in-the-loop checkpoints
  • Logging, tracing and cost observability on every agent run
How we work

From question to production in five stages.

AI projects fail differently from ordinary software projects, so we run them differently. The early stages are about proving the thing is possible with your data before anyone writes production code.

engagement — typical path from first call to live 2–4 weeks to a working prototype
01 Frame

YOU LEAVE WITH

  • A scoped use case
  • An evaluation standard
  • Cost of a wrong answer, agreed
STMLstrategist · ML lead
02 Ground

YOU LEAVE WITH

  • A map of your data
  • Retrieval strategy
  • Security & deployment model
DEMLdata eng · ML lead
03 Prototype

YOU LEAVE WITH

  • A system running on your data
  • Honest accuracy numbers
  • A go / no-go decision
MLBEUXML · backend · UX
04 Harden

YOU LEAVE WITH

  • Eval suite & audit logging
  • Access control and failure handling
  • The full product around the model
BEQAFEfull pod
05 Scale

YOU LEAVE WITH

  • Deployment in your environment
  • Drift and cost monitoring
  • Every artefact transferred to you
OPSQAdevops · QA
2–4 wksTo a working prototype on your data
WeeklyDemos, not status reports
100%Code, weights and evals transfer to you
Your zoneWe work in your time zone and tooling
How to work with us

Three ways to bring us in.

Complete Outsourcing

You bring the problem, we bring everything else. Discovery, data engineering, model work, product design, development, deployment and maintenance — one accountable team, one point of contact, one delivery plan.

Best for founders and business owners without an in-house engineering team

Dedicated AI Pod

A cross-functional squad — ML engineers, backend, frontend, design, QA — working exclusively on your product, in your time zone, with your rituals and tooling. Like an in-house team, at a fraction of the hiring cost and lead time.

Best for funded startups scaling fast, or enterprises spinning up a new AI initiative

Staff Augmentation

Pre-vetted AI and ML engineers who slot into your existing team and start contributing in days, not quarters.

  • Free one-week trial
  • Pre-vetted, senior-level engineers
  • Minimal lead time
  • Availability in your time zone
  • Short-term specialists or long-term extensions

Best for teams with a delivery gap or a specific skills shortage

02 — Platforms & products

Whole products, not proofs of concept.

Model layer, orchestration, interface, infrastructure and governance. One team, one plan, one deployment date.

See what we've built →
delivery plan — M-agnt TSKMR
workstream
MARAPRMAYJUNJULAUGSEP
Discovery
2w
Semantic layer
KPI defs
Retrieval
ingest · index
Agents
dispatch
RBAC & audit
enforcement
Evaluation
harness
On-prem rollout
air-gapped
Monitoring
ongoing
03 — Agents & automation

Agents you can leave running.

Real multi-step work across your tools, with approval gates where it matters and a trace for every run.

agent run — support triagelive
DK
Inbound ticket 08:42:01

Duplicate charges on two consecutive invoices. Customer wants a refund and an explanation.

T
Techtix Agent 6s

Confirmed a duplicate authorisation on 14 Feb. Drafted a refund and a reply, routed to Billing.

crm.lookupbilling.history stripe.refundslack.notify
GateRefunds over £500 need sign-off.
MR
Maya R. approved · 08:44

Refund issued, reply sent, ticket closed.

execution trace — 6.04s4,210 tok · $0.019
receive40ms
classify280ms
crm.lookup1.1s
billing1.4s
reason1.3s
draft1.2s
refund420ms
gateheld
this month
340Tickets / day
6sTo draft reply
100%Runs traced
£500Gate threshold
04 — Models & evaluation

Measured, not asserted.

When the off-the-shelf model is the wrong answer: smaller, cheaper, sharper, and tested on every change.

retrieval.py +7−3
18# route every query through the governed layer
19- def answer(q):
20- docs = index.search(q, k=5)
21- return llm.complete(prompt(docs, q))
19+ def answer(q, user):
20+ kpi = semantic.resolve(q)
21+ docs = index.search(q, k=20, acl=user.roles)
22+ docs = reranker.top(docs, n=5)
23+ out = llm.complete(prompt(docs, q, kpi))
24+ audit.record(user, q, docs, out)
25+ return out.with_citations(docs)
eval — fine-tune vs frontier baseline
techtix-fin-7b — 94% frontier baseline — 71%
11×Cheaper per call
3.1×Faster median
0Off-prem calls
7BSelf-hosted

Open-weight and proprietary models tuned on your data, with curation, labelling strategy and synthetic generation where real data runs thin.

Smaller models that hold accuracy while cutting latency and cost, deployable on hardware you already own.

Eval suites that run on every change, so a prompt tweak or model upgrade cannot quietly degrade quality.

Featured work

AI we've shipped.

AI products across enterprise data, HR, education, health, advertising and consumer apps. A selection below — more on our work page.

Enterprise AI platform

M-agnt

A governed, multi-agent decision layer over enterprise data, built for government and regulated environments. Runs fully on-premise and air-gap capable, with role-based access enforced at query time and an audit trail on every answer.

Multi-agentRAGOn-premGovernance
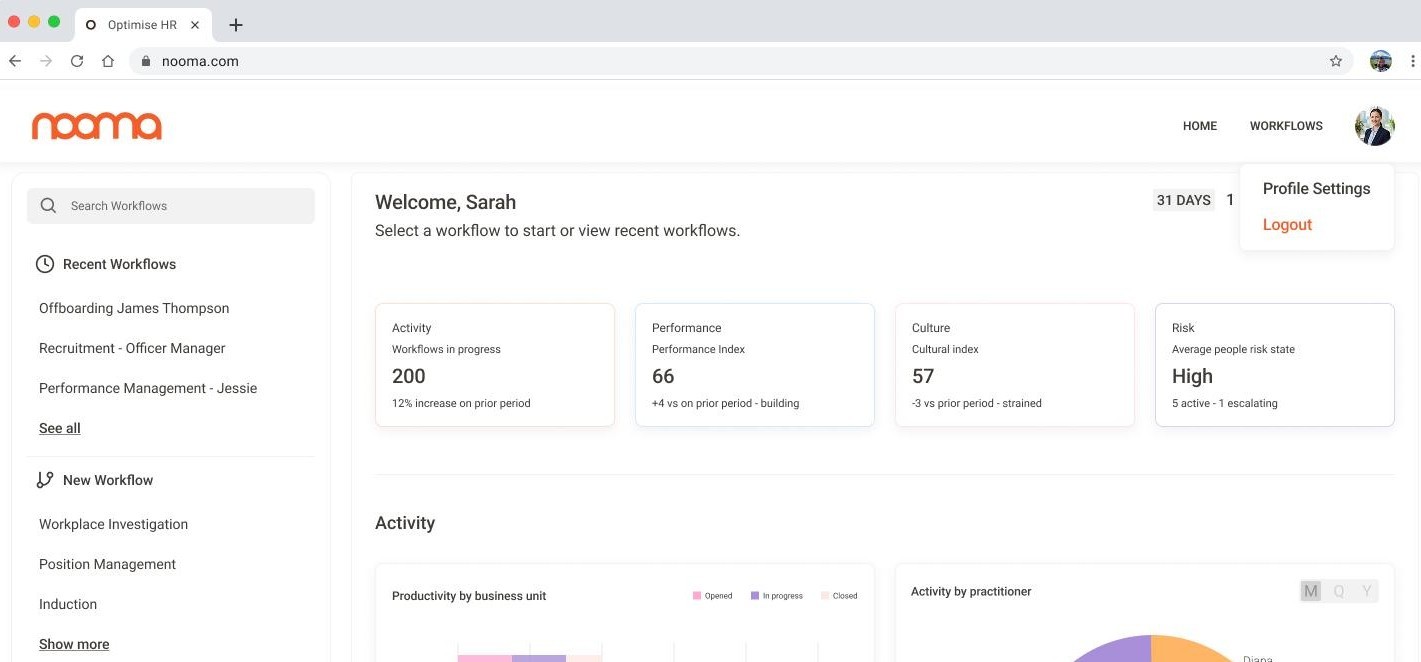
OptimiseHR CHRO dashboard
AI for HR teams

OptimiseHR

Runs HR professionals critical day-to-day work through structured workflows, with human review built into every consequential step rather than bolted on afterwards.

Workflow automationHuman-in-the-loop
Oli Tutor - AI learning companion
AI learning companion

Oli Tutor

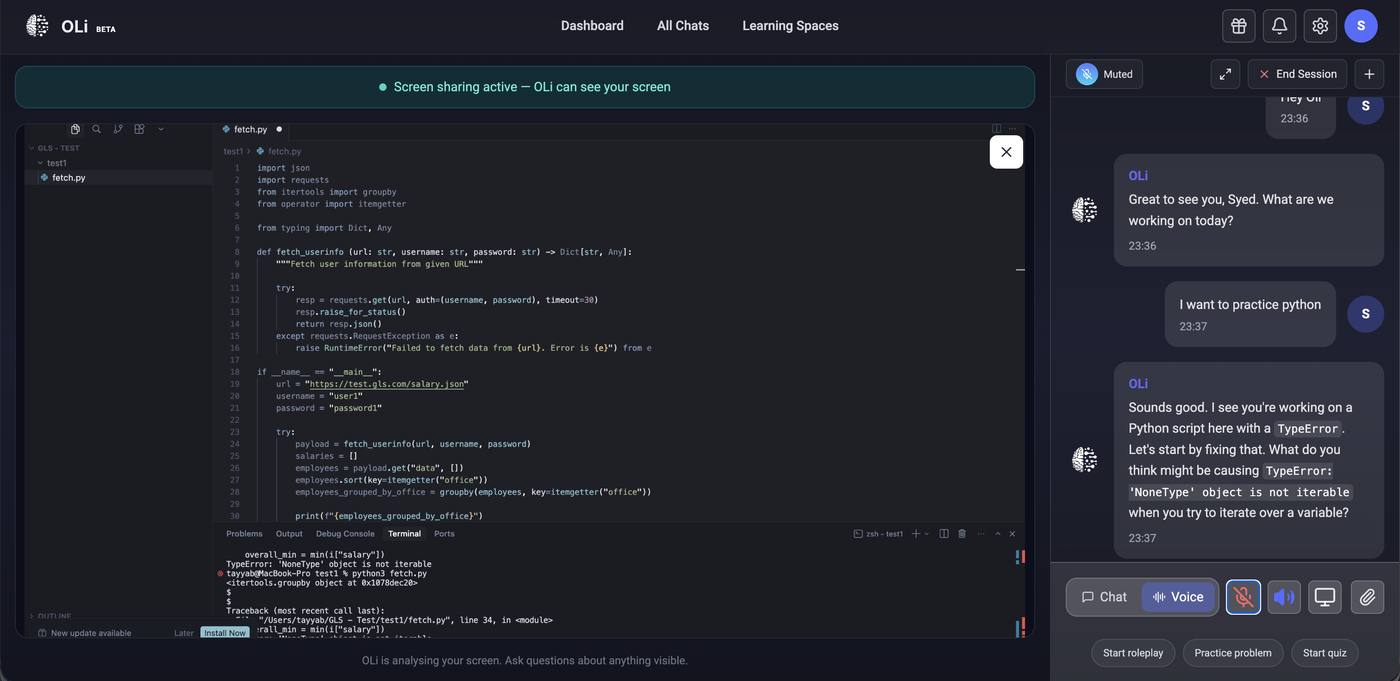
A tutor that sees the learner's screen and speaks with them in native audio, guiding them through material in real time instead of answering questions in isolation.

Native audioScreen readingEdTech
MAIA - Capacity planning intelligence
Capacity planning intelligence

MAIA

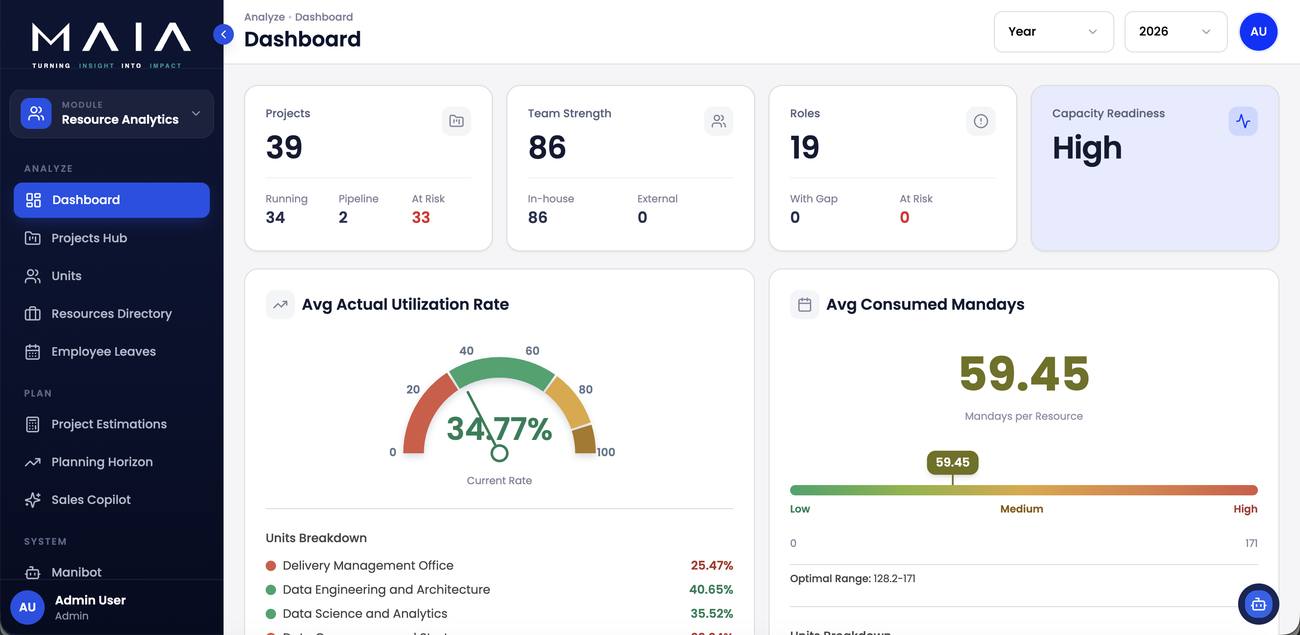
Capacity planning and forecasting for large software organisations, with a conversational layer that answers questions directly from the underlying data and generates custom visuals on request.

NL-to-dataForecastingAI retrofit
AI health tracking

PepTracker

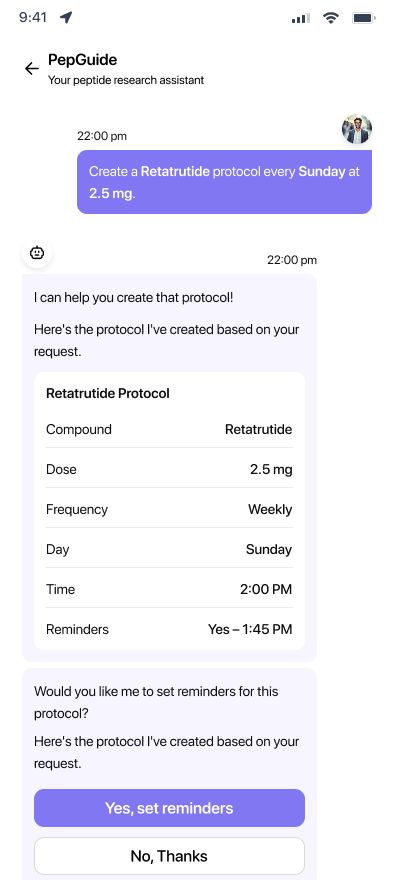
Peptide tracking with protocol scheduling, dose notifications and goal tracking, extended with weekly AI insights and a chatbot that designs protocols through conversation.

  • Weekly insights generated from each user's own dose history
  • Protocols built through conversation, then scheduled and reminded
  • Retrieval scoped strictly to the individual user
Consumer appAI insightsConversational UX
PepTracker - AI health tracking
Our AI stack

The stack behind it.

We are deliberately not tied to one model provider or one framework. Model choice is an engineering decision made per use case — on accuracy, cost, latency and where the data is allowed to go.

Models
OpenAI · Anthropic Claude · Google Gemini · Llama · Mistral · DeepSeek · Qwen · Grok
Frameworks & orchestration
LangChain · LlamaIndex · LangGraph · Model Context Protocol · Hugging Face · PyTorch · TensorFlow · scikit-learn
Retrieval & data
Pinecone · Weaviate · Qdrant · pgvector · Neo4j · Elasticsearch · PostgreSQL · MongoDB · Apache Spark
Infrastructure & serving
AWS · Google Cloud · Azure · Digital Ocean · Docker · Kubernetes · vLLM · Ollama · on-premise and air-gapped deployment
Product engineering
React · Next.js · Node · TypeScript · Python · Go · Flutter · React Native · Swift · Kotlin · GraphQL
Design
Figma · Adobe Creative Suite
Industries

Where we've deployed.

Government & Public Sector
SaaS & Technology
Financial Services
Healthcare & MedTech
Education & eLearning
eCommerce & Retail
Advertising & Marketing
Real Estate & PropTech
Travel & Hospitality
Entertainment & Media
Construction & Engineering
Crypto & Web3
Why Techtix

Why teams pick us over an AI agency.

We were engineers before this

Ten years of shipping production software, long before AI became the headline. That is why our AI systems come with proper architecture, testing and deployment discipline attached.

01

We build where getting it wrong is expensive

On-premise. Air-gapped. Role-based access enforced at the query layer, not the interface. Full audit trails. We have delivered into government and regulated enterprise, and we build to that standard by default.

02

Model-agnostic, and honest about it

We have no reseller incentive. We pick the model that fits your accuracy, cost, latency and data-residency constraints — and we will tell you when the answer is a cheap fine-tuned open-weight model instead of a frontier API.

03

We measure quality instead of asserting it

Every system we build ships with an evaluation suite. You get numbers on accuracy and regression, not a vibe check on a good demo.

04

Design is not an afterthought

An AI feature nobody can figure out how to use has not shipped. Our UX team has been doing this for a decade, and it is why our AI products get adopted rather than trialled.

05

We own the product, not just the ticket

We do not just build products, we treat them as ours — refined, nurtured, and shipped to a standard we would put our own name on.

06
The numbers

We work to drive measurable growth — more revenue, higher valuation, better retention, wider reach, lower operating costs.

10+Years of engineering experience
200+Clients served across the globe
1M+Users on products we have built
$10M+Raised by client startups
60%Faster time-to-market
FAQ

Things buyers ask us first.

Can you deploy without our data ever leaving our infrastructure?

Yes. We build for on-premise and VPC deployment as a first-class option, including fully air-gapped environments with no dependency on external inference APIs. This is a design decision made at the start of a project, not a migration afterwards.

We already have a product. Can you add AI to it without rebuilding?

That is one of the most common things we do. We audit the existing codebase, identify where AI adds real value rather than novelty, and ship incrementally behind feature flags so you can evaluate each addition against the version you already have.

How long before we see something working?

A working prototype against your real data typically takes two to four weeks. Production hardening depends on the compliance and scale requirements, and we scope that honestly after the prototype rather than guessing beforehand.

Which model do you use?

Whichever one fits. We benchmark candidates against your actual use case on accuracy, cost, latency and data-residency constraints. Often the right answer is a smaller fine-tuned open-weight model rather than the most capable API.

How do you stop it hallucinating?

By grounding answers in your data through retrieval rather than model memory, enforcing citation on outputs, and shipping an evaluation suite that measures accuracy continuously. It is an engineering problem with engineering answers, not a prompt trick.

Who owns the code and the models?

You do. All source code, trained model weights, prompts, evaluation suites and documentation transfer to you.

Can you work with our in-house engineering team?

Yes — through a dedicated pod alongside your team, or by embedding individual engineers directly into it. Staff augmentation starts with a free one-week trial.

Contact

Ready to put AI to work?

Tell us what you are trying to build, or bring us a problem you are not sure is solvable yet. Either conversation is welcome.

Incorrect answer, try again.

Techtix
Canada | Turkey | Pakistan
Email
info@techtix.co
Prefer to just talk?
Book a 30-minute discovery call →

AI product engineering,
from prototype to production.

Portfolio

AI products. Built, shipped, running.

Enterprise decision platforms, learning companions, health trackers, ad intelligence, HR automation. Different industries, the same engineering discipline underneath.

Section A Full AI platforms — AI is the product
Enterprise AI platform · Government & regulated enterprise

M-agnt

A governed decision interface that sits over the enterprise's own data. A question in natural language is mapped to approved KPI definitions, specialised agents handle query generation and aggregation, data is retrieved only from permitted sources, and the answer comes back with its query, source and logic attached.

The brief
Enterprise and government teams were losing days to data requests — a ticket, an analyst, a three-to-five-day wait. Generic AI assistants were not an option: no audit trail, no access control, no on-premise deployment.
AI under the hood
Multi-agent orchestration · NL-to-query generation · Governed semantic layer · RBAC enforced at retrieval · Full query audit logging · Air-gap-capable inference
Why it matters
The hardest version of the problem — big data, real compliance obligations, zero tolerance for a confident wrong answer. It is the reference point for how we build everything else.
M-agnt AI platform screenshot

Home · AI briefing and priority signals

AI workflow platform · HR Tech

OptimiseHR

An AI platform that runs HR's critical day-to-day tasks as structured workflows, with a human-in-the-loop checkpoint at every consequential step. The AI does the drafting, screening and synthesis; the human retains the decision.

The brief
HR professionals spend their days on high-volume, high-judgement work. Full automation is inappropriate — the decisions affect people — but the manual workload is unsustainable.
AI under the hood
Multi-step workflow orchestration · Human-in-the-loop approval gates · Document understanding · Structured output generation
Why it matters
A worked example of where the review checkpoints belong. Put them everywhere and you have not saved anyone time; put them nowhere and no one will use the system twice.
OptimiseHR

CHRO dashboard · activity, performance, culture and risk

AI learning companion · EdTech

Oli Tutor

A learning companion with native audio conversation and screen reading, so it follows what the learner is working on and guides them through it in real time — closer to a tutor sitting next to them than a chatbot in a sidebar.

The brief
Chat-based tutoring answers the question a student asks. It cannot see what they are actually looking at, where they are stuck, or what they have misread.
AI under the hood
Native audio input and output · Real-time screen understanding · Multimodal context handling · Low-latency conversational architecture
Why it matters
Native audio and live screen context are genuinely difficult to make responsive enough to feel natural. Getting the latency right was most of the engineering.
Oli Tutor: a learning companion with native audio conversation and screen reading

Live session · OLi reads the learner's editor and terminal, then asks rather than answers

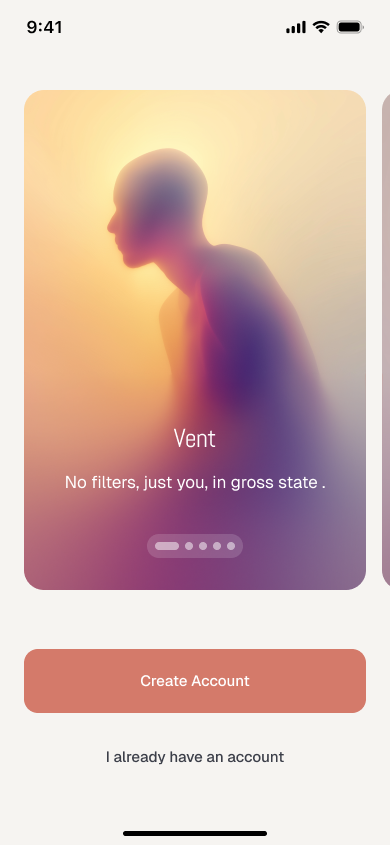
Conversational AI · Consumer

Amia

A chat companion built for genuinely human-feeling conversation — one that holds context across sessions, follows a thread, and helps users understand themselves better over time.

The brief
A consumer app for self-reflection, where the quality of the conversation is the entire product.
AI under the hood
Long-horizon conversational memory · Persona and tone consistency · Context management across sessions
Why it matters
Consumer AI is unforgiving. There is no procurement process protecting you — if the second conversation is worse than the first, the user is gone.
Amia chat companion: a conversation about the user's day, with Amia asking questions and responding to the user's answers

Amia · A chat companion for human-like conversation

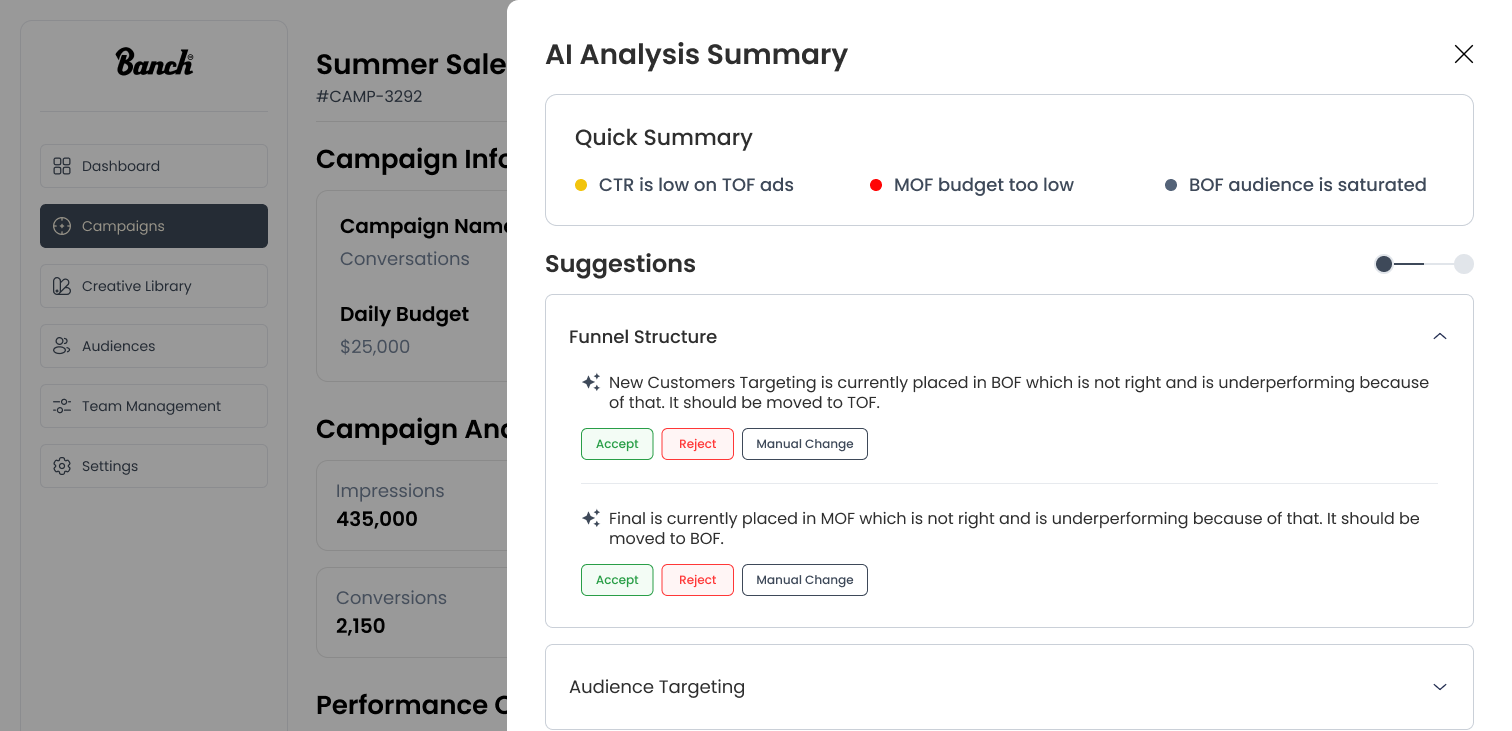
AI for ad campaigns · MarTech · in design / development

Banch

A platform that ingests campaign data, analyses performance, surfaces what is working and what is burning budget, and generates entirely new campaigns with AI.

The brief
Meta ad performance analysis is repetitive, data-heavy work, and campaign creation from scratch is slow.
AI under the hood
Performance analysis over advertising data · Generative campaign creation · Recommendation systems
Banch platform: a dashboard view of ad campaigns, with performance metrics and budget flags highlighted

Concept view · performance analysis and budget flags

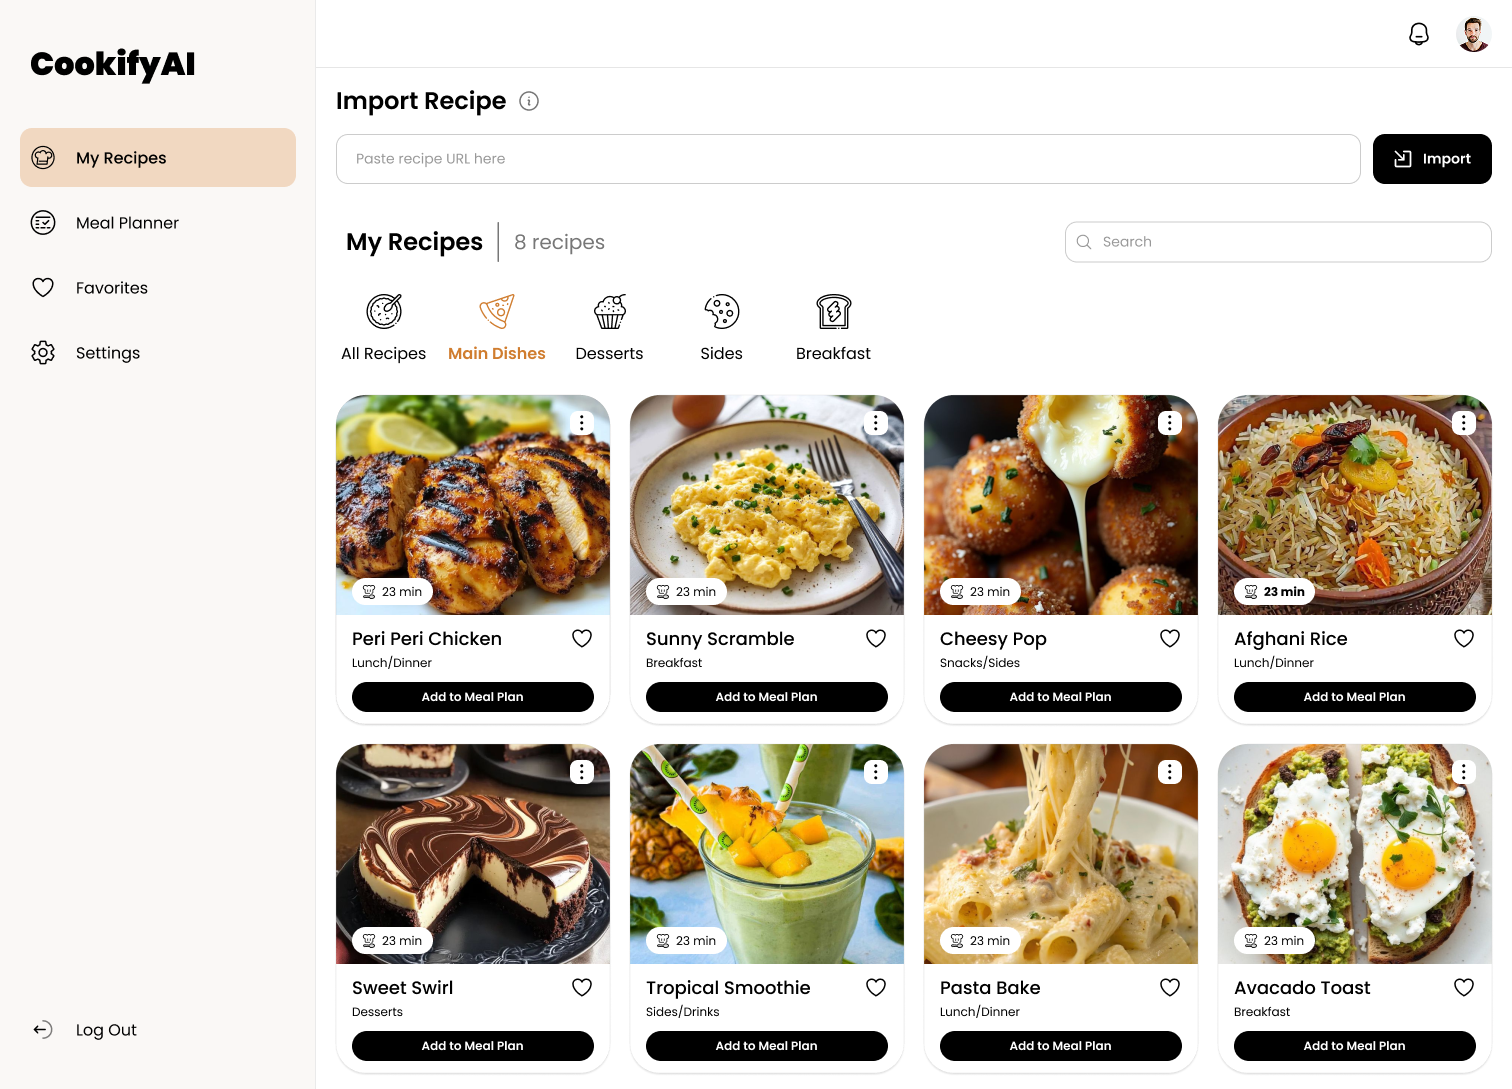
AI consumer app · FoodTech · in design / development

CookifyAI

A meal plan generator that turns saved recipe links into structured meal plans and consolidated shopping lists.

The brief
People save recipes to Pinterest constantly and cook almost none of them, because the gap between a saved link and an actual week of meals is all manual work.
AI under the hood
Web content extraction and parsing · Recipe structuring from unstructured sources · Constraint-based plan generation
CookifyAI: a meal plan view with recipes and ingredients, and a consolidated shopping list

Concept view · seven-day plan and consolidated list

Capacity planning intelligence · AI retrofit

MAIA

A capacity planning and forecasting platform with a conversational layer over the underlying data. Users ask questions in plain language and get answers — and can ask the system to build custom visuals and dashboards on the spot rather than requesting them.

The brief
Large software organisations plan capacity in tools that produce fixed reports. Any question the report was not designed to answer means a ticket to an analyst.
AI under the hood
Natural-language querying over structured data · On-demand chart and dashboard generation · Forecasting models
Why it matters
The clearest demonstration of the retrofit pattern — the planning engine was sound, the interface was the bottleneck.
MAIA

Resource analytics · utilisation, capacity readiness and unit breakdown

Health & wellness app · AI retrofit

PepTracker

An AI layer that generates weekly insights from each user's history, plus a chatbot that answers questions about their doses and past protocols and can build new protocols through conversation.

The brief
A peptide tracking app with protocol scheduling, dose notifications, a peptide library and goal tracking. Solid tracking, but users had to interpret their own data.
AI under the hood
Personalised insight generation from time-series data · Conversational protocol creation · Retrieval over individual user history
Why it matters
Personal health data means retrieval has to be strictly scoped to the individual user, and insight quality has to hold up over months of accumulating history.
PepTracker: a conversation with the AI assistant about the user's peptide protocol, with the assistant surfacing relevant peptides and setting reminders

PepGuide · builds the protocol, sets reminders, then surfaces relevant peptides

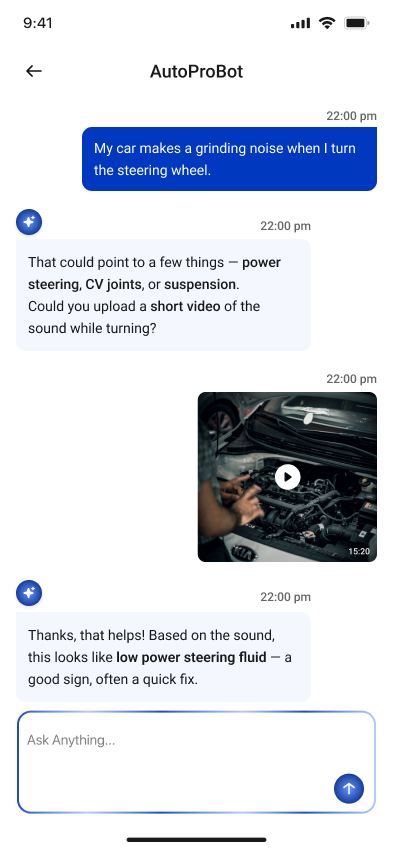
Marketplace app · AI triage · in design / development

AutoProHub

A garage booking app with an AI chatbot that triages the issue first — asking diagnostic questions in plain language, narrowing down the likely fault, and routing the booking with useful information attached.

The brief
Drivers describing a car problem to a booking platform do not know what is wrong. Garages receive vague requests and cannot quote or schedule properly.
AI under the hood
Conversational diagnostic triage · Domain-constrained reasoning · Structured extraction from unstructured description
Why it matters
Narrow, well-scoped AI inside a transactional flow. It does not need to be a general assistant — it needs to be right about cars and fast about it.
AutoProHub conversation triaging a car problem, asking diagnostic questions and routing the booking with useful information attached

AutoProHub · AI-powered car problem diagnosis and booking

The work we can't show

A meaningful share of our AI work sits behind NDAs or inside on-premise government and enterprise deployments that will never have a public URL. If your use case looks like one of those, we can usually walk through the architecture and outcomes on a call under NDA.

Have something you want built?

Bring us a defined product, or a problem you are still trying to scope. We will tell you honestly which parts AI should handle and which parts it should not.